Achieving Ultimate System Stability With SRESchool.in
Introduction
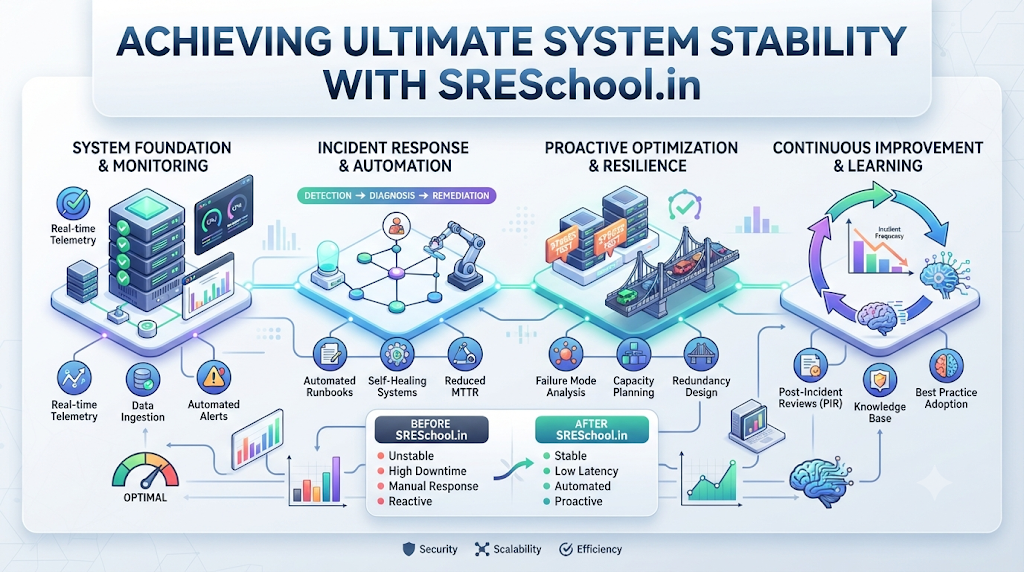
Technical teams frequently battle unexpected server outages and complex software failures that disrupt user experiences. Manual incident handling and constant alert noise drain productivity across development and operations groups. Site Reliability Engineering resolves these hurdles by applying software engineering methods directly to infrastructure management. SRESchool.in provides a comprehensive educational environment that helps technical practitioners build robust and scalable production architectures. Exploring these learning resources equips engineers with the practical knowledge required to maintain continuous uptime.
What Is Site Reliability Engineering and Why Does It Matter?
Site Reliability Engineering establishes a vital bridge between software developers and infrastructure management teams. Developers push new code rapidly, but applications require resilient hosting environments to prevent failures under heavy user demand. Traditional operations models often failed to scale efficiently as company infrastructure grew larger. Site Reliability Engineering introduces proactive monitoring, automation, and systematic troubleshooting to guarantee high availability. This discipline matters because modern users expect flawless digital experiences around the clock. Prioritizing system reliability prevents costly outages and preserves long-term customer trust.
What You Can Discover Through SRE Training
Participating in structured SRE Training empowers professionals to master essential cloud and infrastructure competencies. Learners discover how to configure comprehensive monitoring pipelines and interpret real-time system metrics accurately. The curriculum covers core principles such as service level indicators, service level objectives, and error budgets to quantify system performance. Participants also practice automating routine chores and planning ahead for future infrastructure capacity demands. Troubleshooting production incidents becomes systematic when engineers know how to analyze logs and trace system bottlenecks. These valuable capabilities prepare technical teams for high-pressure operational environments.
What Is SRE Certification and Why Do Professionals Pursue It?
SRE Certification offers a formal way to validate an individual’s theoretical and practical understanding of reliability engineering. Professionals pursue these credentials to test their knowledge and demonstrate a commitment to rigorous industry standards. Certification covers core concepts like incident management, system automation, and scalable architecture design. Certification prerequisites, testing formats, and industry recognition vary depending on the chosen credential provider. Certification alone does not replace hands-on project experience or guarantee immediate career promotions. Instead, it serves as a helpful milestone to support ongoing professional growth.
How to Select the Ideal SRE Course
Choosing an appropriate SRE Course depends entirely on your current technical background, learning objectives, and schedule availability. Beginners should look for structured curricula that start with fundamental Linux and networking concepts before advancing to cloud architecture. A quality course includes practical exercises, real-world troubleshooting scenarios, and clear explanations of observability tools. Reviewing the syllabus ensures the topics align with your specific professional development goals. Taking a gradual, step-by-step approach prevents burnout and helps you absorb complex production workflows smoothly.
What Site Reliability Engineering Training Entails
Site Reliability Engineering Training connects abstract software theory with day-to-day production challenges. Rather than just reading about outages, learners actively analyze simulated system failures and performance degradation. This training cultivates a proactive mindset focused on finding root causes rather than applying temporary patches. Participants discover how to design architectures that recover gracefully when individual components experience issues. Working through realistic scenarios teaches engineers the importance of clear communication and disciplined incident response. This practical preparation empowers technical teams to handle real-world operational stress successfully.
Understanding Site Reliability Engineering Certification Standards
Site Reliability Engineering Certification establishes a structured roadmap for studying modern production operations and system resilience. Preparing for these exams encourages professionals to review core topics thoroughly, ranging from distributed system design to disaster recovery. While certification supports structured learning, it remains only one method among many for building reliability expertise. Practical project implementation, reading technical documentation, and experimenting with infrastructure tools prove equally valuable. Organizations value engineers who demonstrate genuine problem-solving capabilities alongside formal credentials. Balancing exam preparation with practical experimentation yields the best overall outcomes.
How SRE Tutorials Help Accelerate Learning
SRE Tutorials deliver focused, step-by-step instructions for executing specific technical tasks and tool configurations. These guides prove especially useful when you want to set up a monitoring dashboard or write infrastructure code. Tutorials segment complex technologies into manageable steps, allowing you to follow along and test ideas locally in your environment. They frequently provide code snippets, sample configuration files, and quick fixes for common setup errors. Combining tutorials with structured courses reinforces your learning and delivers immediate practical results. Over time, these small practice sessions build immense confidence for larger operational projects.
Understanding SRE Tools and Their Everyday Uses
Modern reliability engineering depends on a diverse ecosystem of software utilities to keep systems visible and manageable. These utilities generally fall into categories such as monitoring, logging, tracing, alerting, and infrastructure provisioning. Monitoring utilities track overall system health, while logging tools record detailed event messages for debugging purposes. Infrastructure management utilities help teams provision cloud resources consistently using code. Tool selections vary widely based on your organization’s technology stack, architecture, team size, and budget constraints. No single utility serves as the universal best choice for every enterprise.
Implementing Effective SRE Best Practices
SRE Best Practices provide a reliable compass for building, monitoring, and maintaining scalable systems efficiently. Establishing clear reliability goals aligns engineering efforts directly with business expectations. Utilizing error budgets allows teams to balance the speed of new feature releases with overall system stability. Automating repetitive manual chores frees engineers to focus on architecture and long-term product enhancements. Writing thorough postmortems after incidents helps teams learn from mistakes without blaming individuals. Because every organization operates differently, teams adapt these practices to match their unique workflows.
What an SRE Engineer Does Daily
An SRE Engineer operates right at the intersection of software development and infrastructure operations. Their daily responsibilities include tracking system performance, triaging production alerts, and automating manual workflows. They write custom scripts to enhance system reliability, build deployment pipelines, and optimize cloud resource usage. When outages occur, SRE engineers help locate root causes, restore service rapidly, and document valuable lessons learned. They collaborate closely with software developers to ensure new features feature proper observability and scalability from day one. This dual focus keeps the role dynamic and exciting.
Understanding SLOs, SLIs, SLAs, and Error Budgets
Reliability metrics help teams evaluate system performance accurately from the user’s perspective.
| Metric Term | Core Definition | Practical Application |
|---|---|---|
| SLI (Service Level Indicator) | A quantitative measurement of service performance, such as latency or error rates. | Quantifies actual system behavior over specific time windows. |
| SLO (Service Level Objective) | A reliability target established for the SLI within a designated timeframe. | Directs internal engineering priorities and alerting thresholds. |
| SLA (Service Level Agreement) | A formal contractual commitment with users concerning uptime and penalties. | Manages external business obligations and customer expectations. |
| Error Budget | The permitted amount of unreliability allowed by the service level objective. | Balances innovation speed with stability; depleting it pauses feature rollouts. |
Using these metrics eliminates guesswork during reliability discussions. Reliability targets depend entirely on specific service requirements, meaning a critical payment portal requires much stricter thresholds than an internal documentation wiki.
How Monitoring and Observability Empower SRE Teams
Monitoring alerts you when a system breaks, whereas observability helps you understand why the failure happened. Metrics, logs, and distributed traces form the core pillars of an observable production environment. Metrics supply high-level numerical data, logs capture detailed event records, and traces follow user requests across microservices. When an alert triggers, SRE teams leverage these data streams to pinpoint the exact origin of a problem. Strong observability minimizes guessing during troubleshooting and accelerates incident resolution times. Setting up purposeful alerts ensures your team catches real issues without suffering from alert fatigue.
Navigating Incident Management and Incident Response
Production incidents represent an inevitable aspect of operating complex software systems at scale. Incident management provides a disciplined framework for detecting, handling, and resolving unexpected outages. When an alert fires, the response team collaborates to mitigate the issue and restore service quickly. Clear communication channels keep internal stakeholders informed during high-priority emergencies. Once the system recovers, the team conducts a postmortem meeting to analyze what happened and why. Focusing on constructive learning rather than assigning blame prevents recurring failures.
How Automation Eliminates Repeated Work
Manual chores consume precious engineering hours and introduce human error into production operations. Automation solves this by writing scripts or programs to execute routine tasks programmatically. Activities like server provisioning, software deployments, security certificate renewals, and database backups are prime candidates for automation. Reducing repeated toil allows engineers to redirect their energy toward proactive system design and architectural improvements. SRESchool.in highlights automation as a cornerstone for building sustainable, scalable engineering workflows. Effective automation makes systems consistent and minimizes manual intervention.
Managing Cloud Reliability and Distributed Systems
Modern software applications frequently run across distributed cloud environments rather than isolated physical servers. Distributed systems introduce distinct challenges, including network latency, partial component failures, and synchronization issues. Cloud reliability involves crafting architectures capable of surviving the failure of individual virtual machines or data centers. SREs employ techniques like load balancing, redundancy, and graceful degradation to maintain continuous uptime. Understanding cloud infrastructure mechanics helps engineers anticipate failure modes and design fault-tolerant applications. This knowledge remains essential for managing modern web-scale platforms successfully.
Supporting SRE Work With Kubernetes and Terraform
Kubernetes and Terraform serve as popular technologies within modern cloud infrastructure management. Kubernetes automates the deployment, scaling, and operation of containerized applications across server clusters. Terraform empowers engineers to define cloud infrastructure using declarative configuration files, known as Infrastructure as Code. These technologies help teams manage complex environments consistently and reduce manual configuration errors. However, not every SRE team deploys Kubernetes or Terraform in their daily operations. Tool choices always depend on the specific technical stack, architecture, and requirements of the organization.
Building a Simple SRE Learning Path
Constructing a solid foundation in Site Reliability Engineering benefits from a structured, progressive approach. You can begin by learning basic Linux administration, networking fundamentals, and scripting languages like Python or Bash. Next, explore core monitoring principles, log management, and how to define basic SLIs and SLOs. Afterward, dive into cloud platforms, containerization basics, and standard incident response workflows. Platforms like SRESchool.in can guide your educational journey from foundational concepts to practical production scenarios. Taking your time with each stage ensures lasting practical competence.
Exploring SRE Training in India
Technology professionals across India increasingly look toward SRE Training to launch careers in modern cloud operations. SRE Training in India helps engineers understand how regional and global enterprises manage large-scale production systems. By focusing on practical competencies like monitoring, automation, and incident response, learners prepare for real-world challenges. This training complements traditional software engineering backgrounds by embedding a strong operational mindset. Focusing on skill development helps professionals adapt smoothly to shifting industry demands.
How SRESchool.in Facilitates SRE Learning
SRESchool.in acts as a dedicated resource platform for individuals exploring Site Reliability Engineering. The site provides educational materials covering SRE Training, SRE Certification preparation, comprehensive SRE Courses, and SRE Tutorials. Learners can explore essential topics including SRE Tools, SRE Best Practices, and the core responsibilities of an SRE Engineer. Whether you seek guidance on defining SLOs, mastering incident management, or understanding cloud reliability, the platform helps structure your educational journey. By offering clear explanations and practical insights, SRESchool.in supports continuous professional growth for technology practitioners.
Why Learning SRE Grows Increasingly Useful
As enterprises migrate more workloads to cloud environments, maintaining system reliability becomes critically important. Businesses cannot sustain prolonged outages that alienate customers and harm revenue streams. The demand for engineers who understand monitoring, observability, and automation expands steadily across industries. Learning SRE principles equips technical professionals with enduring skills regardless of specific vendor tools. This expertise bridges the gap between rapid software development and dependable operational stability. Investing time in mastering reliability engineering opens up fantastic career opportunities in modern tech operations.
Frequently Asked Questions About SRESchool.in
What is SRESchool.in and who is the platform built for?
SRESchool.in functions as an educational learning hub tailored for software developers, system administrators, and IT professionals eager to master Site Reliability Engineering and cloud reliability.
Do I need prior programming experience before starting SRE studies?
Basic scripting knowledge in languages like Python or Bash proves helpful, though beginners can start by learning fundamental Linux administration and networking concepts.
Does SRESchool.in grant official SRE industry certifications?
SRESchool.in operates as an educational training and resource platform, whereas formal certification examinations are administered by respective professional credentialing organizations.
How does SRE training improve day-to-day IT operations?
SRE training teaches engineers how to establish proactive monitoring, automate repetitive manual toil, and handle incidents systematically to reduce stress and downtime.
What types of technologies are covered in SRE tutorials?
Tutorials typically cover utilities related to monitoring, alerting, log aggregation, infrastructure management, container orchestration, and cloud deployments based on the specific lesson.
Is Kubernetes an absolute requirement to become an SRE engineer?
No, Kubernetes is widely popular for container orchestration, but tool choices vary by organization, and core SRE principles apply across diverse infrastructure architectures.
How do SLOs and error budgets benefit software development teams?
SLOs and error budgets provide a shared quantitative metric for reliability, enabling developers and operations staff to balance release velocity with system stability.
What distinguishes monitoring from observability?
Monitoring tells you when a system fails, while observability leverages metrics, logs, and traces to help you determine why the failure happened.
How does SRE training in India assist local technology professionals?
SRE training helps engineers in India cultivate practical skills for managing modern cloud systems, aligning with the rising adoption of DevOps practices across enterprises.
How can I kickstart my SRE learning journey using SRESchool.in?
You can begin by exploring foundational tutorials, mastering core reliability metrics like SLIs and SLOs, and following a structured learning path focused on monitoring and automation.
Final Thoughts
Mastering Site Reliability Engineering transforms how you approach software development and infrastructure management. Prioritizing automation, observability, and proactive problem-solving enables engineers to build systems capable of surviving unexpected failures. Platforms like SRESchool.in supply valuable resources to help learners navigate SRE training, tools, and best practices. Whether you are preparing for certifications or upgrading your daily production workflows, continuous learning remains the ultimate key to success. Embrace the reliability mindset, practice consistently, and enjoy building stable, scalable systems for the future.
Leave a Reply